Embedding a Rule Engine via SDK Without Leaking Domain Logic
Encapsulate rules in the SDK boundary to keep domain logic out of host code.
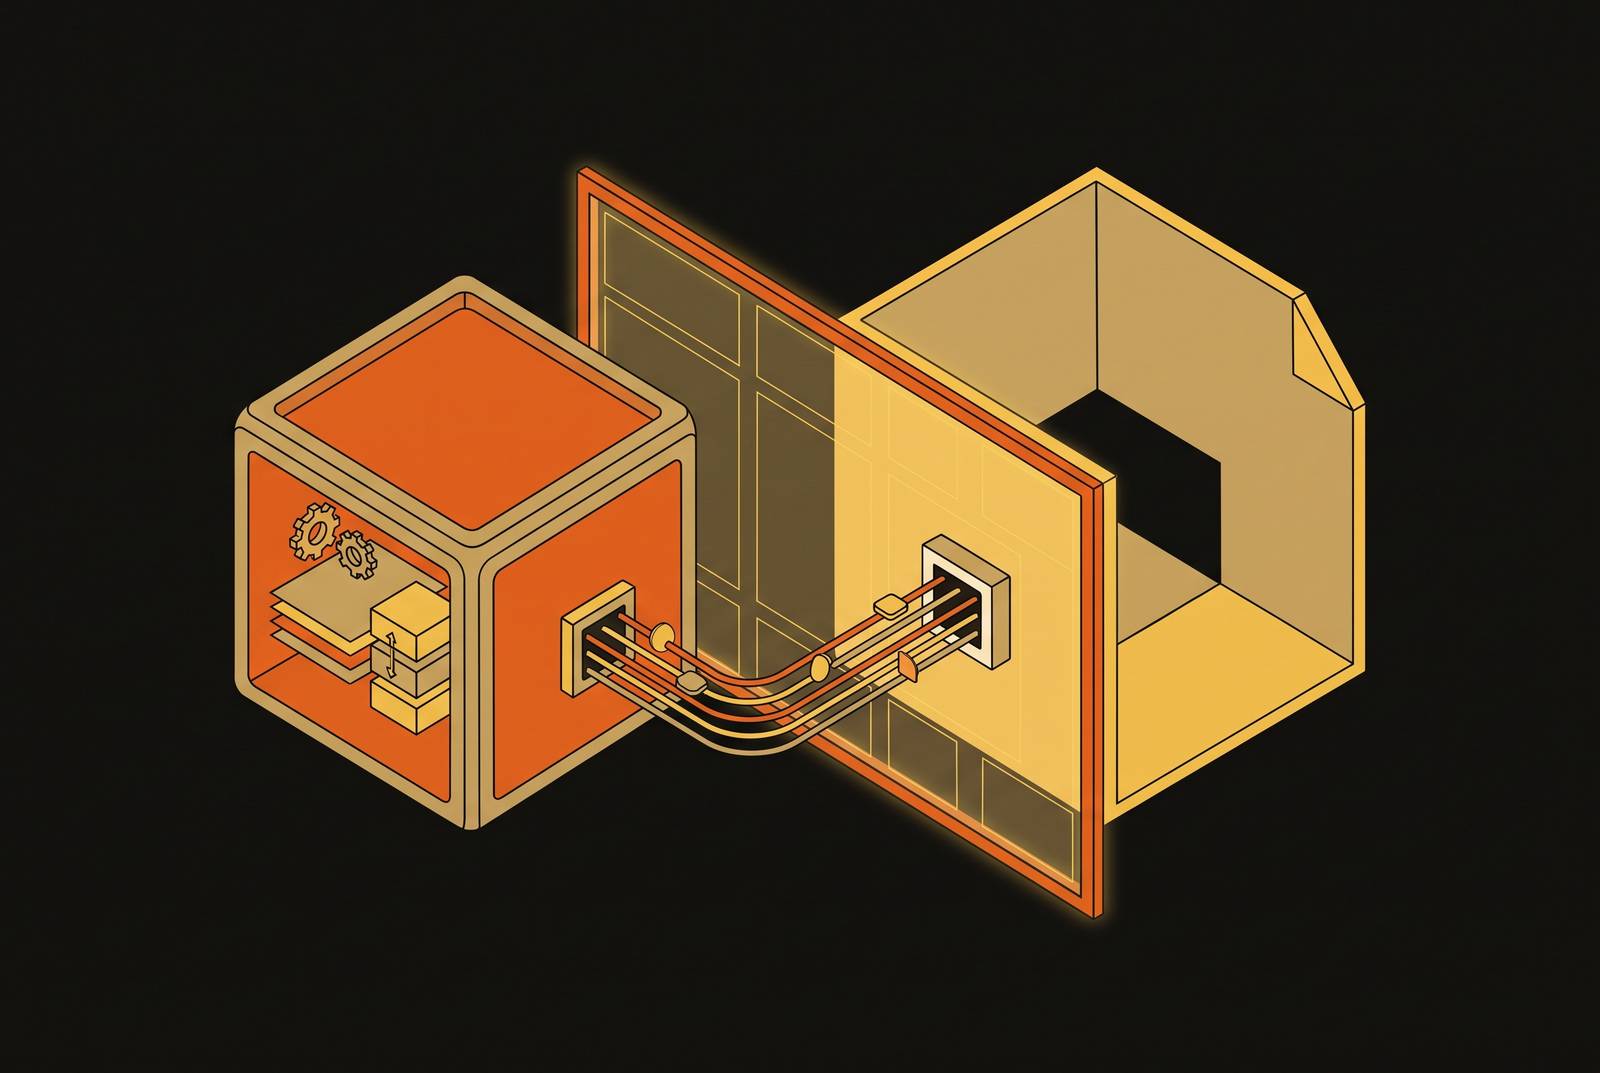
A rule engine embedded via SDK only stays clean if the host treats it like a locked box: facts go in, decisions come out, and nothing about the logic in between leaks back into the calling application. This piece walks through the architecture that makes that possible, so rules stay encapsulated, version-controlled, and changeable without a single line of host code moving. Embedding a Rule Engine via SDK Without Leaking Domain Logic.
Why domain logic escapes the host application
Every host application starts clean. Then a feature ships, and a conditional gets added to handle an edge case. Then another. Each one is defensible on its own.
At a deeper level, the issue is architectural. Object-oriented design wants each domain object to own its own logic: a rack owns its power draw, a cooling zone owns its thermal limits. But real rules rarely respect those boundaries. A single clearance rule might touch power capacity, cooling zone assignment, and cable routing all at once, and none of those three objects is the rightful owner of that combined judgment. Centralizing that logic in a rule engine is a deliberate inversion of encapsulation, done on purpose because scattering the rule would be worse.
Left unaddressed, the rules end up living inside the host, versioned with the host, shipped on the host's release schedule. That means a domain expert who wants to change a threshold, say, adjusting a power limit or a clearance distance, has to file a ticket and wait for a developer to get to it. Worse, that one change now demands regression testing across the whole application, because nobody can be sure what else depended on that number. It is a governance and velocity problem at its core. It's a governance and velocity problem: the people who understand the rules can't touch them, and the people who can touch them don't always understand the rules.
What a rule engine is when embedded via SDK (and what it is not)
When the tooling is stripped away, a rule engine does one thing: it evaluates a set of IF-THEN conditions against input data and fires whatever action matches. The host hands over data. The engine hands back a decision. Match, resolve, act, that's the whole loop; the host only ever sees the first and last step, never the middle.
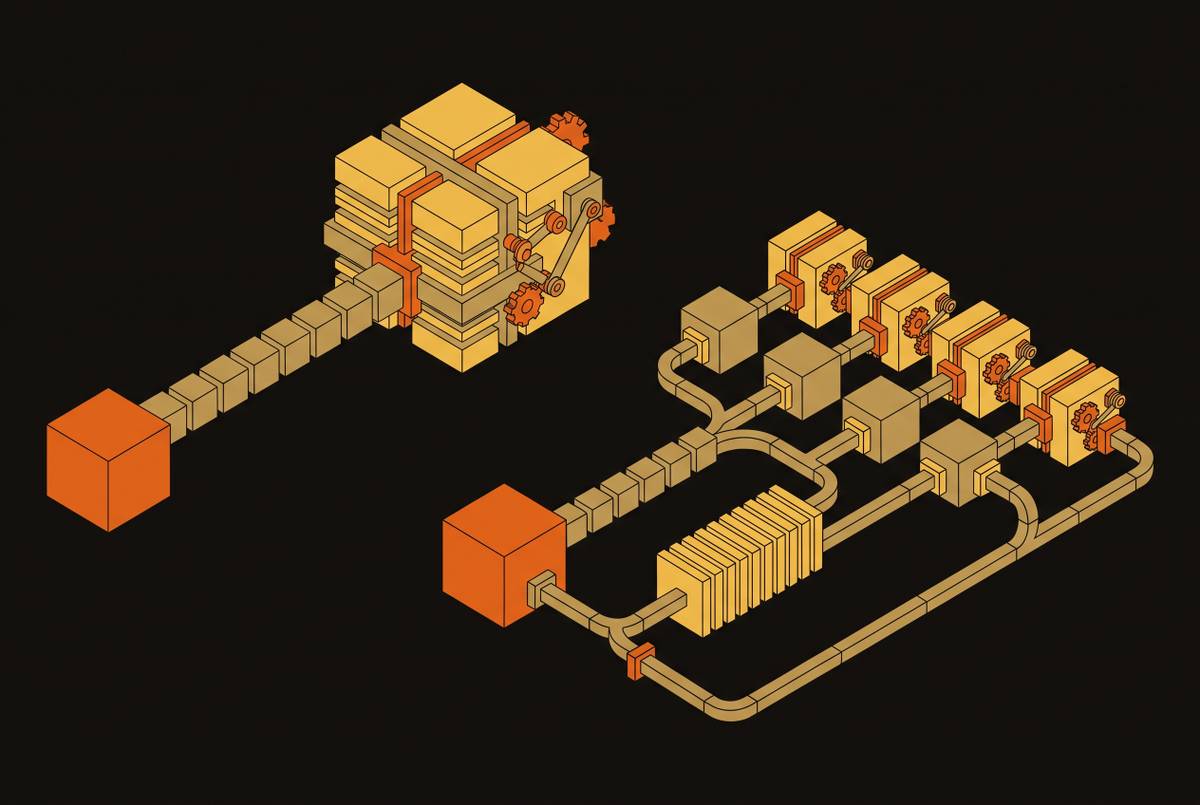
Embedded via SDK means the engine runs inside the host process rather than a remote service. That distinction matters for performance. RuleGo, for instance, documents that it front-loads most of its work during initialization, so once it's running, executing a rule chain adds almost no overhead, which is part of why it holds up even on edge servers with limited resources. Microsoft's RulesEngine takes a similar shape from the other direction: it ships as a NuGet package, but the rules themselves live outside it entirely, in Azure Blob, Cosmos DB, SQL, or file system. OpenL Tablets follows the same logic in Java: it's a library, but it can also be deployed as a web service under a service-oriented architecture, so the host never has to take a compile-time dependency on the actual rule logic CMIC Global - Data Center Construction Trends Wikipedia - OpenL Tablets.
A rule engine produces knowledge, while a workflow engine performs work. It's not a workflow engine. Business rules produce knowledge and workflows perform work, and conflating the two ties a judgment like "this rack layout violates clearance" to one specific process instead of leaving it reusable everywhere that judgment applies CMIC Global - Data Center Construction Trends.
Rule engines are also separate from AI outright. They solve different problems. AI is the right tool where flexibility and language understanding matter, deterministic rules are the right tool where precision, compliance, and traceability are non-negotiable, and swapping one in for the other doesn't make sense in either direction. For engines built on the Rete algorithm, like Drools or NRules, there's a specific performance reason to prefer them at scale: Rete avoids re-evaluating every rule from scratch on every single call, which matters a lot once the host is invoking the engine at high frequency.
The opaque-authority principle: how the SDK boundary enforces encapsulation
The host passes inputs and gets back decisions. It doesn't import the logic, inspect it, or quietly rebuild a copy of it somewhere in its own codebase. The moment host code reads a rule condition, mirrors a threshold, or duplicates a policy constant, the logic has already leaked.
The SDK boundary has a job on both sides of that exchange. Inbound, from host to engine, it carries structured facts, data shaped to whatever contract the engine defined as its expected input. Outbound, from engine to host, it carries decisions and classifications, the engine's verdict, stripped of the reasoning chain that produced it. What it must never carry: raw rule text, condition predicates, rule IDs that the host uses to drive its own control flow, or any piece of the engine's internal state⟧c12⟧.
Business rules literature calls this externalization, the idea that rules can change more often than the rest of the application, and that externalizing them lets business users modify them without waiting on IT. But that promise only holds if the host resists the temptation to re-import the logic through some back door. And there are a few classic ways that happens. One is when host code switches on a rule name or rule ID the engine returned, something like "if the engine returned rule 42, also run X," which quietly couples the host to engine internals that were never supposed to be visible. Another is a duplicated threshold, say a power limit of 20 kW living in the host's own config file right alongside the engine that's supposed to be the sole authority on that number CMIC Global - Data Center Construction Trends. Two sources of truth for the same fact will drift apart eventually, it's basically guaranteed CMIC Global - Data Center Construction Trends. A third is the host pre-filtering what it sends to the engine, deciding on its own that some inputs don't need evaluation. That's the host quietly executing rule logic before the engine ever gets a look at it.
Picture a rack move in a data center that's supposed to cascade automatically through power, cooling, cable routing, and documentation. That cascade breaks the moment any one of those downstream systems keeps its own private copy of the clearance or capacity rule.
Designing the input contract so the host never needs to understand rule internals
The input contract is an SDK-defined schema. The engine publishes the fact types it expects, and the host's only job is mapping its own internal data onto that shape at the boundary. That mapping layer is the one place, and the only place, where host code is allowed to know anything at all about the engine's vocabulary.
What crosses that boundary matters as much as the boundary itself. The host should hand over raw, structured facts, things like rack ID, physical location, connected circuits, current draw, cooling zone, rather than pre-digested summaries like is_over_capacity: true. That flag looks harmless, but it's already a policy judgment, one the engine was supposed to be the one making. Pass it in pre-computed and the rule logic has quietly moved upstream into the host's data prep code, which is exactly the leak this whole architecture exists to prevent.
Adobe's Experience Platform Mobile SDK shows a clean version of this pattern. The SDK defines "data elements," a dictionary of named facts the host registers once, and rules get written against those element names rather than against whatever variable names happen to live inside the host's code. The host never even learns which rule consumed which element, it just feeds the dictionary and moves on.
The same shape applies directly to data center tooling. Equipment specs pulled out of manufacturer PDFs, voltage, amperage, heat load, physical dimensions, should be a structured fact object that the engine consumes directly. They should not land in host code that starts making partial decisions with that data before ever calling the engine. The moment the host starts reasoning about the facts instead of just packaging them, the boundary's already broken.
Designing the output contract so decisions travel without their reasoning
On the way out, the engine should hand back a decision descriptor. A decision descriptor says what to do, or what's true: "layout violates clearance," "circuit requires upgrade," "handoff package incomplete." A rule trace says which rules fired and why, which is genuinely useful for debugging but dangerous the moment production code starts branching on it.
Audit needs belong inside the engine, not exported to the host. The engine can log its own reasoning in its own store, queryable on its own terms whenever someone needs to dig in. The host's job is simpler: record that a decision arrived and record what it did in response. It doesn't need to reconstruct the reasoning, and reconstructing it would mean re-coupling to internals the boundary was built to hide.
Output stability matters just as much as input stability. If the engine returns clearance: FAIL today and switches to clearance_violation: true tomorrow because someone renamed a rule internally, host code breaks for no reason connected to any real change in behavior. The output contract needs to absorb that kind of internal churn rather than exposing it.
Adobe's rules engine also demonstrates something useful about multi-action outputs: a single rule evaluation can trigger several distinct actions, and the engine delivers each one to whatever extension or handler is supposed to receive it, without the host ever having to build that list itself. The host doesn't orchestrate, it just responds.
One anti-pattern appears constantly and deserves calling out directly: the engine returns a raw score, and host code applies the threshold itself, something like "if score > 0.8, reject." That threshold is domain logic, plain and simple, and it belongs inside the engine, not bolted onto the host's response handling. It's the exact same failure as pre-filtering on the input side, just mirrored on the way out.
Storing and versioning rules outside the host deployment pipeline
Keeping the engine binary separate from the rule definitions isn't a deployment detail, it's a first-order architectural decision. Microsoft's RulesEngine is storage-agnostic on purpose, pointing to Azure Blob Storage, Cosmos DB, Azure App Configuration, Entity Framework, a relational database, or a plain file system as valid homes for rules. Engine and rules ship on separate release cycles because they are, functionally, separate products. RuleGo takes the same approach with JSON-defined rule chains that load, and reload, at runtime, entirely outside the compiled binary.
That separation makes independent versioning possible. A domain expert or a compliance lead can update a rule, push it to the rule store, and the running system picks it up without anyone touching the host deployment pipeline. RuleGo goes further and supports hot deployment: business requirements shift and the rule chain updates without restarting the main program. Roll-back becomes a rule-store operation instead of a code revert, which is a meaningfully faster recovery path when something goes wrong.
None of that removes the need for governance. Rule changes still need their own QA gate, externalization doesn't excuse anyone from the usual testing discipline. Versioning should track who changed a rule, when, and under what authority, the same traceability standard that governs RFI answers and design decisions on a critical-facility project. And the rule store needs access controls of its own: who can write changes, versus who can only read or run tests against them.
Licensing deserves a mention here too, because it's easy to overlook until it's a legal problem. OpenL Tablets ships under LGPL 3, which allows it to be used as a library inside proprietary applications without forcing the host to open its own source code, though any modification to the library itself does have to be shared back. The license terms decide whether an engine can be embedded in a commercial SDK without creating obligations on the host product's codebase, and that's worth confirming before anyone commits to a build.
Selecting an embedded engine whose architecture supports clean boundaries
Everything above points toward a short list of things to check before picking an engine. Can rules be stored externally, so they can update independently of the host? Does it publish stable input and output schemas the host can map to without reading rule internals? Does it return decisions by default, with tracing available separately rather than bundled in? Does its performance model match how often the host actually calls it? And does the license fit the host's distribution model without creating unwanted obligations?
A few engines illustrate these tradeoffs concretely. RuleGo, written in Go, uses a component-based architecture with JSON rule chains kept external to the binary, supports hot deployment without a restart, and runs light enough for edge deployments. It fits well when the host is Go-based, the deployment is edge or IoT, and operations teams need to change rules often without waiting on a release.
Microsoft's RulesEngine, distributed as a NuGet package for.NET, stores rule definitions in whatever external store the team already controls, keeping engine and rules explicitly separate so rule changes can't touch the core system's behavior. It's a strong fit for.NET shops already running Azure infrastructure, especially where non-developers need to manage rules without a redeploy.
OpenL Tablets, a Java library with a stable release at 6.4.0 as of August 19, 2026, represents rules in table formats that look close to the spreadsheets and business documents domain experts already use, backed by BRMS tooling like OpenL Studio for direct rule editing, and deployable as a web service under SOA. That's the right pick when domain experts need to author rules themselves in something spreadsheet-like, without a developer standing between them and the change.
Drools and NRules, built on the Rete algorithm, avoid re-checking every rule from scratch on each call, which holds up well under high-frequency invocation and explains their long track record in Java and.NET environments respectively. They make sense when rule sets are large, heavily interdependent, and need real forward-chaining inference across many facts at once.
The same boundary discipline is visible in data center design tools built around these principles, where power capacity, cooling zone limits, and cable routing all need to be governed by rules that live outside the design application itself. Deterministic rules handle the parts where precision can't bend, clearance checks, capacity limits, compliance thresholds, while AI is left to the parts that actually benefit from flexibility, like layout suggestions and documentation that has to adapt to context. Equipment data pulled from manufacturer PDFs flows in as structured facts, not as conditional logic scattered through the host, and when a density standard or a clearance requirement changes, that change propagates through the rule engine without anyone touching the design application at all. That's the whole architecture working as intended: the host stays dumb about the rules, on purpose, and the rules stay free to change without asking the host's permission first.
Sources
- OpenL Tablets
- Business rules engine
- GitHub - rulego/rulego: ⛓️RuleGo is a lightweight, high-performance, embedded, next-generation component orchestration rule engine framework for Go.
- Mobile Core Rules Engine
- Chapter 1. The Rule Engine
- RulesEngine | A fast and reliable .NET Rules Engine with extensive Dynamic expression support
- GitHub - microsoft/RulesEngine: A fast and reliable .NET Rules Engine with extensive Dynamic expression support · GitHub
- Drools